YouTube Recommendations: What Is Documented and What You Can Test
A recommendation system finds videos for a particular viewer. Your channel dashboard shows outcomes of that process, but it does not reveal the system's internal weights or prove why one upload received more distribution.
Revision note: this article now distinguishes YouTube's documentation from editorial hypotheses. Earlier claims about a fixed distribution sequence, universal evaluation windows and Shorts “diluting” an audience model were too strong and have been removed.
What YouTube actually documents
YouTube's performance and discovery FAQ describes recommendations in terms of relevance to viewers and their responses. Watch history, choices about what not to watch, feedback and engagement contribute to that process. Its stated goal includes long-term viewer satisfaction. This is a more useful starting point than treating a video as having one universal algorithm score.
That documentation does not supply a formula you can reconstruct from likes, subscriber count and average view duration. A public explanation of signals is not a list of their exact weights. Treat any claim of a secret numerical threshold with caution unless it is supported by evidence you can inspect.
Start with where the views came from
Search, the home page and suggested videos put a video in different contexts. A search viewer has expressed a query. A home-page viewer is choosing among a broader set of possibilities. YouTube's FAQ describes differences between discovery surfaces; an aggregate number can hide those differences.
Suppose a fictional tutorial first reaches people looking for its exact setup instructions, then later appears to a wider audience. Its overall CTR falls. One hypothesis is that the packaging became less persuasive. Another is that the new viewers have a weaker need for that tutorial. You cannot separate those explanations by looking at the combined CTR alone.
Read metrics as definitions, not verdicts
Impressions CTR concerns views following counted thumbnail impressions. It does not include every possible way someone sees a video. Audience retention concerns what happens after viewers start watching. These answer different questions and use different populations.
A higher CTR does not by itself establish a better viewing experience, and a longer average view does not by itself establish broader appeal. Use the metric that corresponds to your question, then inspect its scope. Avoid comparing a short clip and a long tutorial as if equal average durations would mean equal performance.
A practical investigation sequence
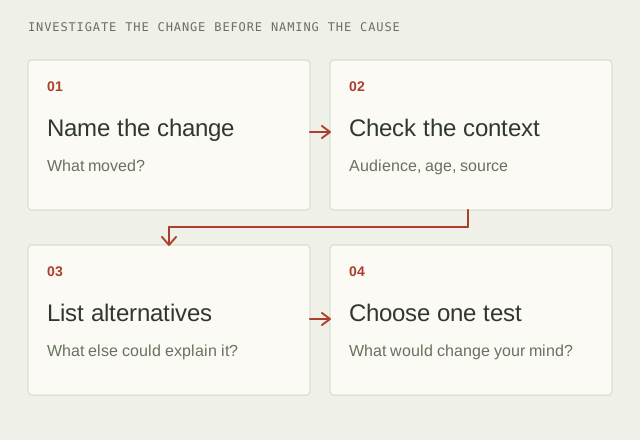
- Name the change. “Browse impressions decreased over the period” is more useful than “the algorithm dislikes the channel.”
- Keep the comparison fair. Record video age, format, topic, traffic source and any changes you made.
- Check the content promise. Watch the opening against the title and thumbnail. Record a specific mismatch rather than a general judgement.
- List alternatives. Topic demand, audience composition, competing events and packaging can all be plausible explanations. The dashboard alone may not distinguish them.
- Make one testable decision. Use a native packaging test when eligible, or seek targeted feedback about the opening. Keep what you held constant in the record.
The research worksheet holds source observations and competing explanations. The Test Planner helps specify a packaging experiment. These tools organise a question; neither provides access to recommendation weights.
Three claims to avoid
“The first hour decides everything.” YouTube's FAQ does not establish a universal first-hour cutoff. It says publication time is not known to determine long-term performance, while timing can matter for live events and early viewing. Schedule for the viewers and format, then inspect the result over a period appropriate to the question.
“One weak upload poisons the channel.” The FAQ describes responses to videos and viewers rather than a simple permanent penalty attached to one unsuccessful upload. This does not mean audience preferences never change; it means a penalty is not established by one disappointing result.
“Shorts automatically damage long-form discovery.” Do not infer a channel penalty or a diluted internal model from a change in format mix. Different formats may attract different viewers. Check your own audience overlap and the purpose of each format before deciding what to make.
What you can conclude from a competitor video
You can record its visible structure, wording, examples and pacing. You normally cannot see the impressions it received, the native alternatives it was tested against or its private retention curve. A successful public video is a source of hypotheses, not proof that a particular editing decision caused success.
Try the research notebook method: one observation, one interpretation and one counterexample. This produces a decision you can explain without claiming to reverse-engineer a private system.
How long should you wait?
There is no universal waiting period that makes every video comparable. State the observation window and why it fits the format. A live event, a seasonal topic and an evergreen tutorial can have different useful windows. Keep uncertainty visible instead of replacing it with an unsupported seven-day or thirty-day rule.
Compare CTR and Retention Without Mixing Audiences
A practical way to investigate packaging and viewing behavior without treating aggregate metrics as proof of causation.
Growth & AlgorithmThe First 24 Hours After Upload: What Matters, and What Is Folklore
Best posting times, comment-reply sprints, the "golden hour". Some of the launch-day advice creators follow religiously has a real mechanism behind it. Most of it does not. Here is the split.
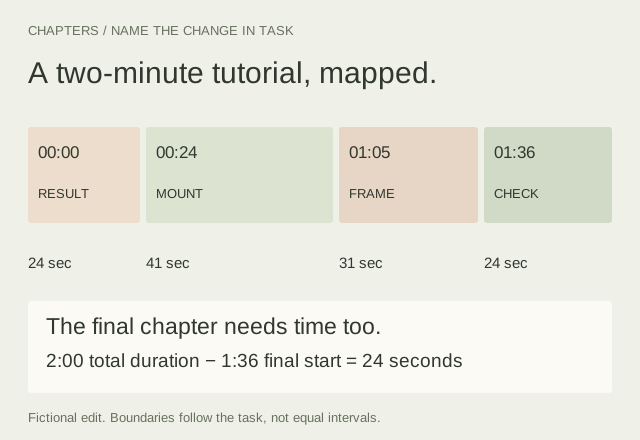
Plan Useful Chapters for a Finished Video
Map a two-minute edit, name the changes in task and check the final chapter as carefully as the first. Includes a blank chapter worksheet.